Key takeaways
- Jev is designed for typed probabilistic decisions over application state — not chat.
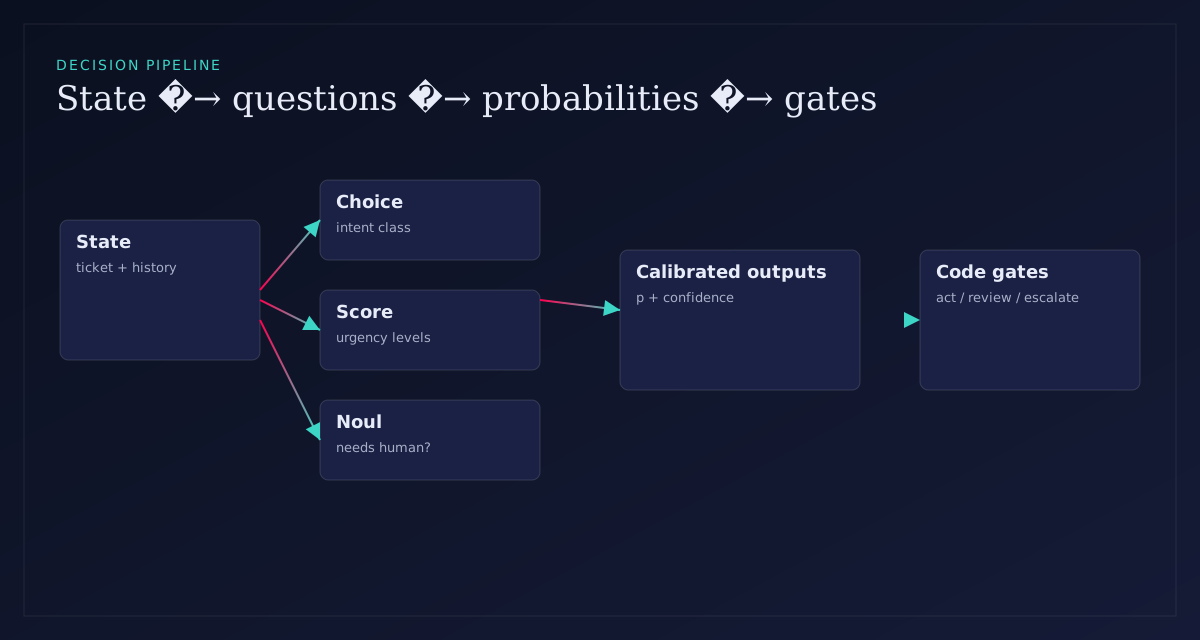
- TypeSafe’s primitives are Choice, Score and Noul; your code owns branching.
- Vendor claims about latency and cost are extraordinary; independent numbers are more conditional.
- The winning pattern is composable systems: decide with a decision model, generate with an LLM.
Why this matters
If you build agents or workflow automation in 2026, you already feel the tax of using a generative model as a Swiss Army knife. Every classification becomes a prompt. Every gate becomes another completion. Every retry burns latency budget and money. The system works until cardinality rises, schemas drift, or the model politely refuses in prose when your orchestrator expected a label.
Jev enters that conversation as TypeSafe’s first public System One model: a model class TypeSafe describes as optimised for fast, structured decisions software can consume directly. LangChain’s September 2026 harness post treats the same capability as middleware inside agent loops — routing and safety — rather than as a replacement planner.
This article is Workstation’s independent introduction. We explain the interface, translate the primitives into original examples, and mark clearly what is a vendor claim versus what independent evaluators have published.
Background
TypeSafe’s founder narrative starts from a blunt question: models have been superhuman at chat for years, so where is the automation? Their answer is not “yet another larger chat model”. It is a stack aimed at automation — architecture, parallel sampling, and a training approach they call Reinforcement Learning for Calibrated Decisions (RLCD). Those are TypeSafe’s claims about their research programme.
The name System One is an explicit homage to Kahneman’s fast thinking. The name Jev nods to Jevons: efficiency that increases demand. Useful metaphors — and also marketing. Engineers should care more about the contract: state in, typed answers with probabilities out.
TypeSafe reports that Jev aims for similar intelligence on System One shaped tasks while being far faster and cheaper than generative LLMs on those tasks — and that it “can’t hallucinate” because outputs are constrained to predefined structures.
Whenever we say “TypeSafe reports”, we are summarising their blog or docs — not asserting an independent Workstation reproduction.
How it works
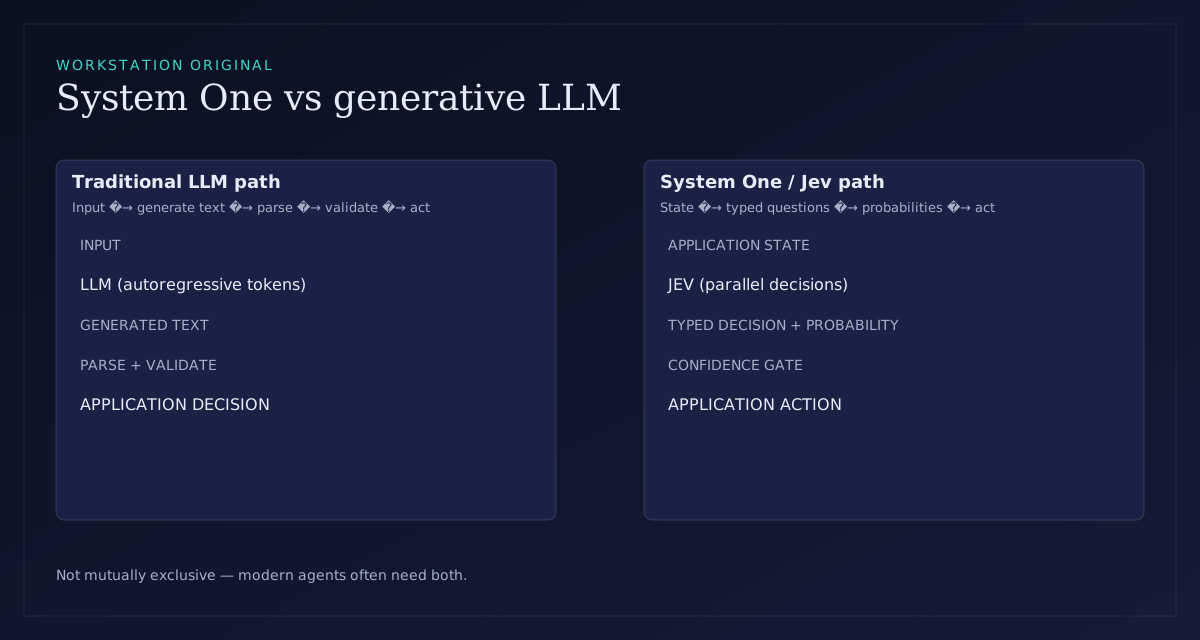
A generative automation path looks like this: gather context, prompt an LLM, receive text, parse, validate, maybe repair, then act. Each stage is a seam. A System One path collapses the middle: your application declares the decision vocabulary; the model returns a distribution over that vocabulary; your application applies thresholds, escalations and side effects.
Official docs describe a single evaluation endpoint pattern: POST a model id, a state payload, and a map of questions. Early-access aliases such as jev-latest resolve to a versioned model id that you should log. Community write-ups around mid-to-late September 2026 commonly reference jev-1.13.x class versions — always confirm against TypeSafe’s models list at call time.
Choice — closed-set routing
Choice is the workhorse for intent routing, repository area classification, and any enum your product already understands. Workstation example: a platform incident bot classifying pages into capacity, dependency, code regression, config, or unknown. The distribution matters as much as the argmax — a 0.41/0.39 split is an escalation signal, not a confident route.
# Pseudocode — Workstation example (not TypeSafe sample verbatim)
response = system_one.ask(
  state={"alert": alert_text, "service": svc, "last_deploys": deploys},
  questions={
    "area": Choice({
      "capacity": "Resource saturation or quota",
      "dependency": "Upstream/downstream failure",
      "regression": "Likely bad deploy/code",
      "config": "Flag, secret, or env drift",
      "unknown": "Insufficient evidence",
    })
  }
)
if response.confidence("area") < 0.7:
  escalate(response)
else:
  route(response.best("area"))
Score — ordered severity
Score fits ordered rubrics: urgency, change risk, toxicity severity, retrieval relevance tiers. Unlike a free integer, ordered descriptive levels force the product team to define what “high” means in domain language — which is exactly where automation usually fails.
Noul — probabilistic yes/no
Noul returns P(statement is true). It is ideal for gates: “Is this tool call irreversible?”, “Is the draft answerable from retrieved context?”, “Did the agent stall?” Your code turns probabilities into allow/deny/escalate. LangChain’s Auto Mode framing is essentially this pattern industrially packaged for tool risk.
Architecture implications
The important shift is ownership. In generative automation, the model often owns both judgement and presentation. In System One automation, the model owns judgement under a schema; presentation and side effects stay in code. That makes it easier to test, easier to audit, and easier to combine with deterministic policy.
It also means you cannot ask Jev to “write the migration plan”. If your workload is generative, you still need a generative model. If your workload is a million micro-decisions, a generative model may be the wrong instrument even when it is accurate.
Evidence landscape (as of the cutoff)
TypeSafe publishes workflow evaluations that place Jev on a Pareto frontier against strong references — with explicit caveats that workflows were authored by their capabilities team and that reference answers lean on particular frontier models. LangChain reports low-variance judging behaviour in a LangSmith replay setting. OpenRouter publishes triage tables with near-tied accuracy and large cost/latency gaps on small sets. AyAutomate’s independent OpenRouter run finds Jev competitive with small models on accuracy while trailing a frontier baseline on high-cardinality routing — and notes that TypeSafe’s headline 193×/444× figures do not appear against those small-model baselines.
Workstation’s Benchmark Lab indexes those sources with source-kind tags. We also ship methodology demos that show how we will measure intent routing, tool safety and failure detection — clearly labelled as methodology until a live measured run is published as Benchmark v1+.
Where it works
- Intent, topic and queue routing at high volume.
- Pre-tool safety classification in agent harnesses.
- Confidence-gated escalation to humans or stronger models.
- Post-generation judges for answerability, citation support and policy.
- Feature extraction style map-reduce over corpora when questions are narrow.
Where it does not
- Code generation, long-form writing, multimodal captioning.
- Problems whose label set cannot be specified ahead of time.
- Situations where you need chain-of-thought artefacts for compliance narrative (unless you store separate generative rationales).
- Any deployment that skips offline evaluation and treats vendor calibration as destiny.
Production considerations
- Pin or log versioned model ids; aliases move.
- Version your question criteria like you version prompts.
- Store raw distributions, not only argmax labels.
- Separate network latency from service latency in dashboards.
- Build human review paths for low-confidence bands.
- Re-run golden sets when models or criteria change; keep historical benchmark versions.
What we know / what we don’t
We know the API shape and primitive types from public docs. We know multiple organisations are integrating decision-model calls into agent middleware. We do not know long-run price sustainability (TypeSafe itself says pricing durability needs time). We do not know your task distribution until you measure it.
Extended implementation notes
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 1: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 2: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 3: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 4: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 5: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 6: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 7: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 8: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 9: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Additional engineering context for What is Jev?: treat every automation seam as a product surface with owners, SLOs and offline labels. When integrating decision models, log versioned model ids, criteria hashes and gate outcomes. Compare against fast LLMs and reasoning LLMs on the same items before standardising. Cite TypeSafe or LangChain when repeating their claims; cite OpenRouter, AyAutomate, LangSmith or JevBench when using their numbers; never present those numbers as Workstation measurements. Connect this page to the Benchmark Lab and Model Selection Manual for next actions. Note cluster 10: prefer shadow mode, then canary, then enforce. Re-evaluate after each model alias move.
Conclusion
Jev is not “a smaller LLM”. In TypeSafe’s framing it is a different product surface for intelligence: decisions with probabilities. Used carefully, that surface can remove an entire class of brittle parse-and-pray automation. Used carelessly, it becomes another unmeasured classifier with prettier JSON.
Related on Workstation
Sources
- TypeSafe AI — Introducing System One Models & Jev — Vendor announcement.
- LangChain — Building a Harness with Jev — Harness patterns.
- TypeSafe docs index — Official primitives and API.
- LangChain — Jev as agent evaluator — Judge variance experiment.
- OpenRouter — Jev vs LLM — Triage tables.
- AyAutomate independent benchmark — 791 decisions.
- JevBench RESULTS — Public harness.
- OpenAI — Introducing the Agents API — Agent platform context in the wider landscape.