Key takeaways
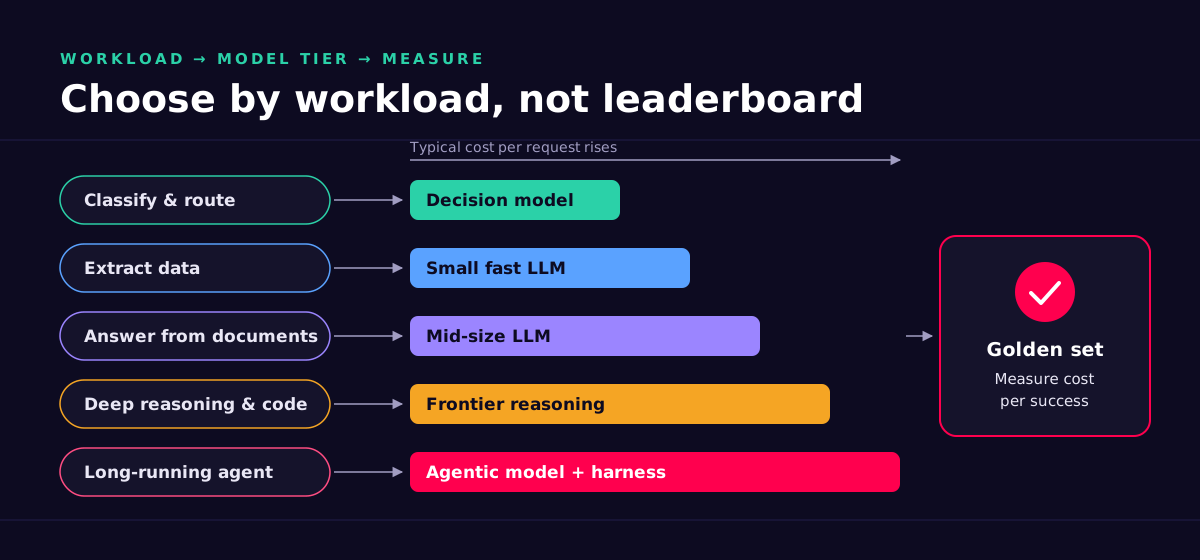
- Start from the workload, not the launch blog.
- Use the cheapest model that passes a measured quality bar.
- Split steps that both decide and generate; route the easy ones to small models.
- Measure cost per success on your own data, and re-test monthly.
Why this matters
Model selection fails when teams chase leaderboards. Workloads differ, so the best model differs too. This guide gives you a framework, not a permanent ranking of brands.
Workload first
Name the step. Does it decide, extract, answer or act?
Cheapest that passes
Set a quality bar, then pick the cheapest model that clears it.
Measure, don’t guess
Test on your own labelled data. Keep every eval version.
Choose a model type in 60 seconds
Interactive
Model chooser
Pick a workload, set your budget and volume, and see which model tier to evaluate first. The chart shows where your budget per request lands.
What is the step doing?
Budget, volume and constraints
Your starting point
Bands are illustrative orders of magnitude at about 1,500 tokens per request (per task for agents). They are not quotes. Check current provider price lists.
Evaluate first
Mid-size generalist LLM
The step writes answers people read. Quality matters, but most requests do not need multi-step reasoning.
- Measure
- Answer quality
- Budget per request
- 0.83p
- Typical API spend / month
- £120–£1,200
Fits your budget. Your budget per request sits inside this tier’s typical band.
Decision framework
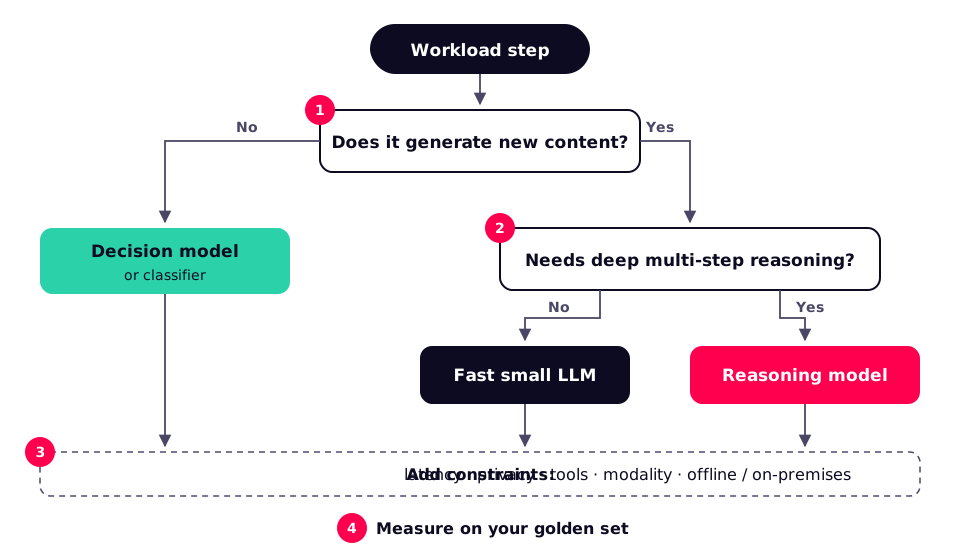
- Does it generate?If the step only decides (yes/no, a label, a route), start with a decision model or classifier.
- Does it reason deeply?If it generates and needs multi-step reasoning, use a reasoning model. If not, a fast small LLM may be enough.
- Add constraintsLatency target, privacy, tool use, modality, and whether it must run offline or on-premises.
- MeasureRun the candidate on your golden set before you commit.
Selection matrix
Treat each row as a starting hypothesis. The colour shows the model tier.
- Decision model
- Small fast LLM
- Mid-size LLM
- Frontier reasoning
- Agentic + harness
Classification
Decision model / classifier
Measure Accuracy + latency
Routing
Decision model
Measure Correct routing + escalation quality
Tool safety
Decision model
Measure False negatives
High-volume automation
Fast decision model
Measure Cost × accuracy
RAG evaluation
Judge / decision model
Measure Calibration
Simple extraction
Small/fast LLM or decision model
Measure Accuracy / cost
Real-time voice
Fast multimodal
Measure End-to-end latency
RAG generation
LLM
Measure Answer quality
Creative writing
Generative LLM
Measure Quality rubrics
Coding
Coding / agentic model
Measure Task success
Deep reasoning
Reasoning model
Measure Correctness
Long-running agent
Agentic frontier model + harness
Measure Task completion
The journey of a typical AI developer
Interactive
From prototype to production
Most AI developers walk the same path. Click a stop to see what happens, which model fits at that stage, and the trap to avoid.
- Explore
- Build
- Run
Prove the idea works
- What you do
- Wire the happy path end to end with one capable hosted model.
- Model choice
- One frontier model for everything. Speed of learning beats cost here.
- Trap to avoid
- Shipping the prototype model to production unchanged.
What to measure
Sixteen dimensions, in four groups. Most steps only care about a few of them, so pick those and ignore the rest.
Quality
- Intelligence & reasoning depth
- Task-specific accuracy
- Coding ability
- Calibration
Speed & cost
- Latency & tail latency
- Cost & cost per success
- Rate limits
- Context window needs
Integration
- Structured output reliability
- Tool use / MCP fitness
- Multimodal needs
- Observability hooks
Risk & operations
- Privacy / data residency
- Deployment model
- Reliability & uptime
- Safety tooling
Worked example: from journey to model policy
- Map the journeyWrite down the user journey and list each step that decides or generates.
- Assign a typeGive each step a candidate model type from the matrix. Skipping this is how teams spend premium reasoning tokens on yes/no gates.
- Write the metricOne metric per step. Only then pick a vendor.
- Name an ownerEach step gets a named owner, so model policy changes land in a human inbox.
- Split and hardenIf a step both decides and generates, split it. High volume: invest in calibration. Irreversible: invest in false-negative analysis and human escalation, not only model IQ.
- Re-run monthlyRe-run a fixed eval harness every month and store the results beside the policy document.
Production checklist
- Keep a written model policy, and version it.
- Pin explicit model ids in production paths that encode thresholds, not moving aliases.
- Revisit the policy when providers change defaults.
- Track cost per successful task, not cost per token.
- Keep historical eval versions so you can compare like with like.
Conclusion
The right model is the cheapest model that meets a measured quality bar under your latency and risk constraints. Sometimes that is a Jev-like decision model, sometimes a frontier reasoner, and often both in one system.
Related on Workstation
- Benchmark Lab — Interactive charts
- Model routing — Send each request to the right model
- Guardrails and tool safety
- AI data centre planner — Run models privately
- AI Agents
Sources
- TypeSafe AI — Introducing System One Models & Jev — Primary vendor source (15 Sep 2026).
- LangChain — Building a Harness with Jev — Harness integration (17 Sep 2026).
- TypeSafe documentation index — Concepts, primitives, API, cookbooks.
- LangChain — Can Jev Be a Better Agent Evaluator? — 20 Sep 2026 LangSmith experiment.
- OpenRouter — Jev vs LLM when to use each — Published triage cost/latency/accuracy.
- AyAutomate — Independent Jev benchmark — 791 decisions; challenges headline multipliers vs small models.
- JevBench RESULTS v1.2 — Public community harness.
- OpenAI — Introducing the Agents API — Landscape: agent platform primitives.