Every Release Earns Production: Making Promotions Boring and Safe
Ordered rings int → test → acc → prod, health gates, version verification, auto-rollback, and humans still controlling production
 Balinder Walia2026年9月10日6 min read
Most release incidents are not exotic. Someone skipped a ring “just this once”. A health check returned 200 while the old build was still answering. A promotion ran after the client disconnected and left the cluster half-updated. Or production was reached because an auto-promote flag was left on somewhere it should not have been.
Ring Promoter treats promotion as a protocol: ordered rings int → test → acc → prod, live health gates, optional version verification, automatic rollback, and a full history for every hop. Tagline: Every release earns production. The control plane is deliberately small — one binary, configuration-driven apps, and a REST API built so CI can fail closed with curl --fail.
Watch the full Ring Promoter demo on YouTube — one application promoted live through all four rings in a single session.
The problem with ad-hoc promotion
Platform teams inherit a patchwork of scripts, pipeline stages, and tribal knowledge. Integration might be a namespace; acceptance might be a spreadsheet; production might be a Slack approval that nobody can replay six months later. That works until it does not — usually on a Friday afternoon or during an incident when the person who “knows the runbook” is offline.
- Skipped environments — a hotfix jumps straight to prod because “test is behind” or the staging cluster is in an unknown state.
- Green that lies — the deploy job succeeded, the endpoint answers 200, but the new version never became the process answering traffic.
- 2 a.m. rollbacks — someone has to remember the previous image tag and the exact command that undoes the last hop, under paging pressure.
- No attributable history — who moved which version where, and did it hold? Chat logs are not an audit trail.
- Mixed estates — Kubernetes services and VM apps with their own GitHub Actions pipelines use different promotion rituals, so “are we safe to go?” means different things for each team.
CI already builds and tests. What is missing is a control plane that moves what CI produced through environments with the same discipline every time — boring on purpose, so release decisions stay about risk and readiness rather than about which script to run.
How it works in 60 seconds
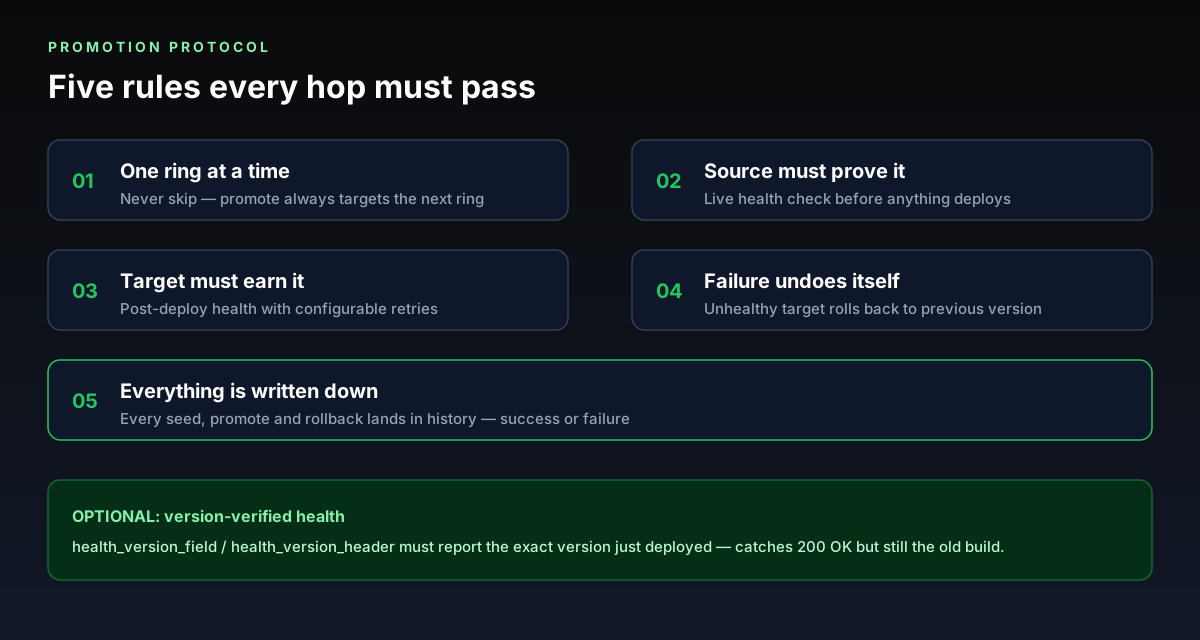
Ring Promoter is a small, production-grade control plane: one Go binary with web UI, JSON REST API and promoter in a single process. It runs on k3s/Kubernetes and stores current/previous version and full history per (application, ring).
- One ring at a time —
promote {from_ring}always targets the next ring. Skipping is impossible by design. - Source must be healthy — a live health check gates the start of every promotion.
- Target must earn it — after deploy, health checks run with configurable retries.
- Optional version verification — the health endpoint must report the exact version just deployed (
health_version_fieldorhealth_version_header). - Failure undoes itself — if the target stays unhealthy, it rolls back to its previous version automatically. Every seed, promote and rollback is written to history.
Safety by default
Promotion is not a shell script you hope someone ran carefully. The control plane serialises per-app operations with a Postgres session advisory lock, so correctness holds across replicas — scaling the control plane up cannot start two promotions on the same app at once. Operations run in a context detached from the HTTP request and bounded by operation_timeout — a client disconnect or load-balancer timeout cannot abort an in-flight deploy or its rollback. State is updated as soon as a deploy lands, so it never lags the cluster even if a later health check fails.
That combination is what makes the protocol safe enough for Friday afternoons: the rules are enforced in one place, not rediscovered in each team’s pipeline YAML.
Automatic rollback
When post-deploy health fails after all retries, Ring Promoter rolls the target ring back to its previous version and records the failure. You do not depend on someone remembering last week’s tag at 2 a.m. The same protocol that promoted the version is what undoes it.
Full audit trail
Every seed, promote and rollback lands in history — success or failure — per application and ring. The UI surfaces live jobs with step-level status and logs. When a job fails, AI-assisted diagnosis (listed on ringpromoter.com) can summarise the persisted evidence rather than guessing from a truncated CI log.
Humans stay in control of production
Two controls keep production deliberate:
- Production password (
RP_PROD_PASSWORD) — required to promote into prod, seed prod, or enable auto-promote into prod. Rollbacks are deliberately exempt so incident response is never blocked. - Auto-promote per ring — a version that lands healthy can continue hop by hop inside the same operation and lock, and stops at the first ring with the flag off. Typical setup: on for
test(so int → test carries on to acc), off foracc(so nothing reaches prod without a human). Config may not setauto_promote: trueon the ring before prod; that is refused at start-up so config cannot bypass the password.
Optional promotion gates (maintenance windows, QA Go-No-Go for the exact version, change-request codes, Grafana go/no-go) run before any deploy, so a failed gate leaves state untouched.
Kubernetes and VMs in one place
The deployer is chosen per application:
- KubectlDeployer —
kubectl set image+ rollout status via the in-cluster ServiceAccount. - GitHubActionsDeployer — for VM apps with existing CI/CD (for example wslproxy on OpenResty). Dispatch, wait, then the same health check and auto-rollback.
- k8sjob — each operation as a Kubernetes Job with runner contract env vars and live log streaming.
One control plane can promote cluster services and VM pipelines side by side.
Config-only onboarding
Add an application with YAML only — no plugin, no SDK, no rebuild. Declare where each ring lives and how to check health, apply the ConfigMap, and the app appears in the console. Apps only define the rings they actually live in. Adding a ring is a single-line change in the ordered pipeline; promotion order, API and UI follow.
CI-friendly API
After CI builds and pushes, seed int and promote with ordinary HTTP. Sync by default returns 200 on success or 422 when the operation ran but failed (so curl --fail works). Use ?async=1 for a job ID with live step-by-step progress.
curl --fail -sS -X POST "$RP/api/apps/$APP/seed" \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -d "{\"ring\":\"int\",\"version\":\"$VERSION\"}"

curl --fail -sS -X POST "$RP/api/apps/$APP/promote" \
  -H "Authorization: Bearer $TOKEN" \
  -d '{"from_ring":"int"}'
Who it is for
Engineering managers, heads of platform, CTOs and DevOps leads who need release discipline without another sprawling toolchain. Platform engineers who are tired of owning one-off promote scripts per app. SRE teams who want rollback to be automatic and attributable. If your pain is skipped environments, lying green checks, and opaque rollbacks — not “we need more dashboards” — this is the control plane for that job.
It does not replace your build system. It does not pretend every organisation has identical rings. It enforces a small set of rules that make promotions safe enough to run when people are tired — which is when most release mistakes happen.
Where to go next
Watch the full demo, then visit ringpromoter.com. For the implementation detail — gates, deployers, locks, and the REST contract — read the technical deep dive.