MongoDB 生產環境中的高可用性:副本集、分片和 Kubernetes 運算子
具有副本集、分片和 Kubernetes 運算子的 MongoDB HA
 Balinder Walia2026年4月12日16 min read
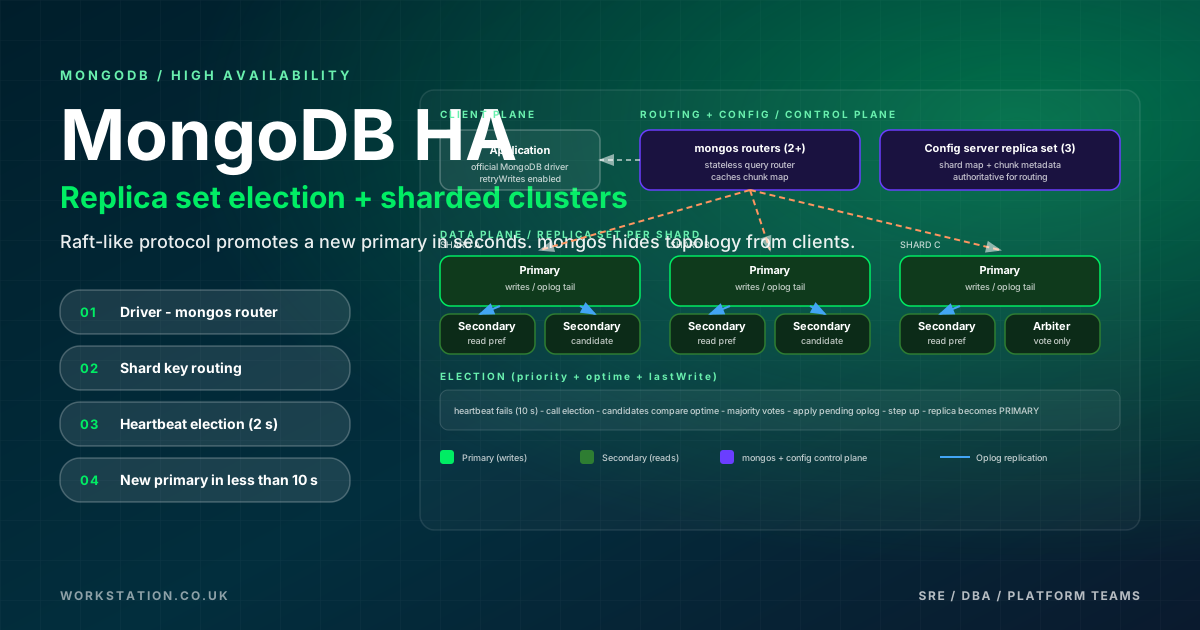
MongoDB 在資料庫領域佔據著獨特的地位。它的文件模型自然地對映到應用程式物件,其靈活的模式無需遷移即可適應不斷發展的資料結構,其內建的複製和分片原語為關聯式資料庫需要外部工具才能實現的高可用性和水平擴充套件奠定了基礎。但地基並不是一座完工的建築。在生產中執行 MongoDB 並實現真正的高可用性(節點故障、網路分割槽或整個區域離線不會導致停機或資料丟失)需要深思熟慮的架構、仔細的調整和嚴格的操作紀律。
本指南介紹了 MongoDB HA 的每一層:從支援自動故障轉移的副本集共識協議和 oplog 複製,到支援水平擴充套件的分片叢集架構,到自動化生命週期管理的 Kubernetes Operator,以及使用 Rancher 的 AWS、Azure、GCP 和裸機 k3s 上的部署選項。每個部分都包括具體配置、YAML 清單以及您可以適應您的環境的操作過程。
MongoDB 副本集架構
副本集是 MongoDB 高可用性的基本單位。它是一組維護相同資料集的mongod程序。其中一個成員是主,它接收所有寫入操作。其餘成員是輔助,它們透過跟蹤其操作日誌 (oplog) 來從主伺服器複製資料。如果主節點變得不可用,副本集會進行選舉,從符合條件的輔助節點中選擇新的主節點 - 通常在 10 到 12 秒內。
生產副本集應至少具有三個資料承載成員,最好分佈在不同的故障域(可用區、機架或資料中心)。這確保了副本集能夠在任何單個成員丟失的情況下倖存下來,並且仍然保持多數用於選舉目的。可選的仲裁器參與選舉,但不儲存資料 - 它的存在只是為了在擁有偶數個資料承載成員時打破平局,儘管 MongoDB 最佳實踐是使用奇數個資料承載成員。
Oplog 和複製機制
oplog 是一個有上限的集合 (local.oplog.rs),它以冪等形式記錄主節點上的每個資料修改操作。輔助節點不斷跟蹤主節點的 oplog 並在本地應用操作。 oplog 大小決定了輔助節點在需要完全重新同步之前可以落後多遠 — 對於生產工作負載,請將 oplog 大小設定為容納至少 24 到 72 小時的寫入活動。 MongoDB 4.4+ 支援透過replSetResizeOplog動態調整 oplog 大小。
# Check current oplog size and window
rs.printReplicationInfo()

# Resize the oplog to 50 GB
db.adminCommand({ replSetResizeOplog: 1, size: 51200 })

# Check replication lag on secondaries
rs.printSecondaryReplicationInfo()
選舉和基於 Raft 的協議
MongoDB 4.0+ 使用 Raft 啟發的共識協議進行副本集選舉。當輔助裝置檢測到主裝置不可達時(預設electionTimeoutMillis為 10,000 毫秒),它可能會發起選舉。要獲勝,候選人必須獲得大多數投票成員的選票。如果多個候選者符合資格,則具有最新 oplog 條目和最高優先順序的成員獲勝。您可以透過設定成員優先順序來影響選舉結果 - 具有priority: 0的成員永遠無法成為主要成員,這對於分析副本或遠端區域中的成員非常有用。
# Initiate a 3-member replica set
rs.initiate({
  _id: "rs-production",
  members: [
    { _id: 0, host: "mongo-0.mongo-svc:27017", priority: 10 },
    { _id: 1, host: "mongo-1.mongo-svc:27017", priority: 5 },
    { _id: 2, host: "mongo-2.mongo-svc:27017", priority: 5 }
  ],
  settings: {
    electionTimeoutMillis: 10000,
    heartbeatTimeoutSecs: 10,
    chainingAllowed: true
  }
})

# Check replica set status
rs.status()

# Step down the primary (for maintenance)
rs.stepDown(60)   // step down for 60 seconds

# Force reconfiguration (emergency)
rs.reconfig(newConfig, { force: true })
讀偏好和寫關注
讀取首選項控制驅動程式傳送讀取操作的位置。選項有:
primary— 所有讀取都轉到主儲存器。最強的一致性,但沒有讀取擴充套件。primaryPreferred— 讀取將轉到主節點(除非它不可用),然後再轉到輔助節點。secondary— 所有讀取均傳輸至輔助裝置。提供讀取縮放,但可能返回過時的資料。secondaryPreferred— 讀取將轉到輔助裝置,除非沒有可用的輔助裝置。nearest— 無論角色如何,讀取都會轉到網路延遲最低的成員。最適合地理分散式部署。
寫入關注控制在操作返回到客戶端之前必須有多少副本整合員確認寫入。
w: 1— 只有主器件必須確認。速度最快,但如果主資料庫在複製之前發生故障,則存在資料丟失的風險。w: "majority"— 大多數資料承載成員必須確認。這是推薦的生產預設值。它保證寫入在初選中倖存下來。w: <number>— 必須確認特定數量的成員。j: true— 在確認之前必須將寫入提交到磁碟日誌。與w: "majority"結合,提供了最強的耐用性保證。
# Connection string with write concern and read preference
mongodb://mongo-0:27017,mongo-1:27017,mongo-2:27017/appdb?replicaSet=rs-production&w=majority&j=true&readPreference=secondaryPreferred&readPreferenceTags=region:us-east

# SRV connection string (DNS-based discovery)
mongodb+srv://appuser:password@cluster.example.com/appdb?w=majority&retryWrites=true&readPreference=nearest
MongoDB 分片叢集架構
副本集提供高可用性,但不提供水平寫入擴充套件 — 所有寫入都傳送到單個主資料庫。當您的資料集超出單個伺服器的容量或您的寫入吞吐量超出一臺主伺服器的處理能力時,您需要分片。分片叢集使用分片鍵將資料分佈在多個副本集(分片)上,從而實現儲存和寫入吞吐量的水平擴充套件。
分片叢集具有三種元件型別。mongos路由器是無狀態查詢路由器,可將客戶端操作定向到適當的分片。至少部署兩個以實現冗餘。配置伺服器形成一個儲存叢集後設資料的副本集 - 哪些塊位於哪些分片上、分片鍵範圍和平衡器狀態。分片伺服器是副本集,每個副本集儲存分片資料的子集。
片鍵選擇
分片鍵是分片叢集中最重要的決定。它決定資料如何跨分片分佈,並直接影響查詢效能、寫入分佈和擴充套件能力。好的分片鍵具有高基數(許多不同的值),在分片之間均勻分佈寫入,並透過有針對性的操作而不是分散聚集來支援最常見的查詢模式。
# Enable sharding on a database
sh.enableSharding("appdb")

# Shard a collection with a hashed shard key (even distribution)
sh.shardCollection("appdb.events", { "event_id": "hashed" })

# Shard with a ranged shard key (supports range queries)
sh.shardCollection("appdb.orders", { "customer_id": 1, "order_date": 1 })

# Check shard distribution
db.orders.getShardDistribution()

# View chunk distribution across shards
use config
db.chunks.aggregate([
  { $group: { _id: "$shard", count: { $sum: 1 } } },
  { $sort: { count: -1 } }
])常見的分片鍵策略包括:用於統一寫入分佈的雜湊鍵(當您不需要對分片鍵進行範圍查詢時最好)、將粗略分組欄位與高基數字段相結合的複合鍵(例如,用於多租戶應用程式的{ tenant_id: 1, _id: 1 })以及基於區域的鍵使資料放置與地理區域保持一致。
多區域
區域分片區域分片將分片鍵的特定範圍限制到特定分片,從而實現資料區域性性。例如,您可以確保歐洲客戶資料駐留在歐盟地區的分片上,而美國客戶資料駐留在美國地區的分片上。
# Add shards to zones
sh.addShardTag("shard-us-east", "US")
sh.addShardTag("shard-eu-west", "EU")
sh.addShardTag("shard-ap-south", "APAC")

# Define zone ranges
sh.addTagRange("appdb.customers",
  { "region": "US", "customer_id": MinKey },
  { "region": "US", "customer_id": MaxKey },
  "US"
)
sh.addTagRange("appdb.customers",
  { "region": "EU", "customer_id": MinKey },
  { "region": "EU", "customer_id": MaxKey },
  "EU"
)
sh.addTagRange("appdb.customers",
  { "region": "APAC", "customer_id": MinKey },
  { "region": "APAC", "customer_id": MaxKey },
  "APAC"
)

# Verify zone configuration
sh.status()
多區域 MongoDB 部署
將 MongoDB 分佈在多個區域有兩個目的:災難恢復(在整個區域丟失後仍能倖存)和延遲最佳化(從最近的副本提供讀取服務)。 MongoDB 透過跨區域分佈的副本整合員、資料區域性性的區域分片以及將讀取路由到最近成員的讀取首選項配置來支援多區域部署。
在分佈在三個區域(2 個在主區域、2 個在 DR 區域、1 個讀取區域)的五成員副本集中,主區域的丟失仍然留下三個可用成員 — 足以讓大多數成員選舉新的主區域。 讀取區域中的成員應具有priority: 0,以防止其成為主要成員(高跨區域延遲會降低寫入效能)。將hidden: true用於不應接收常規應用程式讀取的分析專用成員。
MongoDB 社群 Kubernetes 運營商
MongoDB 社群 Kubernetes Operator 在 Kubernetes 上部署和管理 MongoDB 副本集。它是 MongoDB Inc. 的開源 Operator,負責處理 StatefulSet 管理、自動副本集配置、TLS 證書輪換、使用者管理和滾動升級。
# Install the MongoDB Community Operator via Helm
helm repo add mongodb https://mongodb.github.io/helm-charts
helm repo update

helm install community-operator mongodb/community-operator \
  --namespace mongodb \
  --create-namespace \
  --set operator.watchNamespace="*"
MongoDB社群 CRD 規格
MongoDBCommunity自定義資源定義 MongoDB 副本集的所需狀態。以下是可投入生產的規格。
apiVersion: mongodbcommunity.mongodb.com/v1
kind: MongoDBCommunity
metadata:
  name: production-mongodb
  namespace: databases
spec:
  members: 3
  type: ReplicaSet
  version: "7.0.12"

  security:
    authentication:
      modes: ["SCRAM"]
    tls:
      enabled: true
      certificateKeySecretRef:
        name: mongodb-tls-cert
      caCertificateSecretRef:
        name: mongodb-ca-cert

  users:
    - name: appuser
      db: admin
      passwordSecretRef:
        name: mongodb-appuser-password
      roles:
        - name: readWrite
          db: appdb
        - name: clusterMonitor
          db: admin
      scramCredentialsSecretName: appuser-scram
    - name: backup-user
      db: admin
      passwordSecretRef:
        name: mongodb-backup-password
      roles:
        - name: backup
          db: admin
        - name: restore
          db: admin
      scramCredentialsSecretName: backup-scram
    - name: monitoring
      db: admin
      passwordSecretRef:
        name: mongodb-monitoring-password
      roles:
        - name: clusterMonitor
          db: admin
      scramCredentialsSecretName: monitoring-scram

  additionalMongodConfig:
    storage.wiredTiger.engineConfig.cacheSizeGB: 4
    storage.wiredTiger.engineConfig.journalCompressor: snappy
    storage.wiredTiger.collectionConfig.blockCompressor: snappy
    net.maxIncomingConnections: 10000
    operationProfiling.mode: slowOp
    operationProfiling.slowOpThresholdMs: 100
    replication.oplogSizeMB: 51200
    setParameter.cursorTimeoutMillis: 600000

  statefulSet:
    spec:
      template:
        spec:
          containers:
            - name: mongod
              resources:
                requests:
                  cpu: "2"
                  memory: 8Gi
                limits:
                  cpu: "4"
                  memory: 16Gi
            - name: mongodb-agent
              resources:
                requests:
                  cpu: 250m
                  memory: 256Mi
                limits:
                  cpu: 500m
                  memory: 512Mi
          affinity:
            podAntiAffinity:
              requiredDuringSchedulingIgnoredDuringExecution:
                - topologyKey: topology.kubernetes.io/zone
                  labelSelector:
                    matchLabels:
                      app: production-mongodb-svc
          tolerations:
            - key: "workload"
              operator: "Equal"
              value: "database"
              effect: "NoSchedule"
      volumeClaimTemplates:
        - metadata:
            name: data-volume
          spec:
            storageClassName: gp3-csi
            accessModes: ["ReadWriteOnce"]
            resources:
              requests:
                storage: 100Gi
        - metadata:
            name: logs-volume
          spec:
            storageClassName: gp3-csi
            accessModes: ["ReadWriteOnce"]
            resources:
              requests:
                storage: 10Gi
該規範建立了一個執行 MongoDB 7.0 的三成員副本集,具有 SCRAM 身份驗證、TLS 加密、獨立的資料和日誌卷、跨可用區的 Pod 反關聯性以及適用於具有 16 GB RAM 的節點的 WiredTiger 調整。當您更改version欄位時,操作員將處理副本集初始化、成員配置和滾動升級。
適用於 MongoDB Operator 的 Percona 伺服器
MongoDB 的 Percona Operator(PSMDB Operator)為 Community Operator 提供了功能更豐富的替代方案。它部署 Percona Server for MongoDB(帶有附加企業功能的 MongoDB 的直接替代品),管理分片叢集和副本集,透過 Percona Backup for MongoDB (PBM) 整合備份,並支援時間點恢復。
# Install Percona Operator
helm repo add percona https://percona.github.io/percona-helm-charts/
helm repo update

helm install psmdb-operator percona/psmdb-operator \
  --namespace psmdb \
  --create-namespace
# Percona Server for MongoDB Cluster CRD
apiVersion: psmdb.percona.com/v1
kind: PerconaServerMongoDB
metadata:
name: production-psmdb
namespace: databases
spec:
crVersion: "1.16.0"
image: percona/percona-server-mongodb:7.0.12-7
imagePullPolicy: IfNotPresent
replsets:
- name: rs0
size: 3
resources:
requests:
cpu: "2"
memory: 8Gi
limits:
cpu: "4"
memory: 16Gi
volumeSpec:
persistentVolumeClaim:
storageClassName: gp3-csi
accessModes: [ReadWriteOnce]
resources:
requests:
storage: 100Gi
nonvoting:
enabled: false
arbiter:
enabled: false
configuration: |
storage:
wiredTiger:
engineConfig:
cacheSizeGB: 4
journalCompressor: snappy
collectionConfig:
blockCompressor: snappy
operationProfiling:
mode: slowOp
slowOpThresholdMs: 100
replication:
oplogSizeMB: 51200
affinity:
antiAffinityTopologyKey: topology.kubernetes.io/zone
sharding:
enabled: false
mongos: {}
configsrv: {}
backup:
enabled: true
image: percona/percona-backup-mongodb:2.5.0
storages:
s3-backup:
type: s3
s3:
bucket: company-mongodb-backups
region: us-east-1
credentialsSecret: aws-s3-credentials
prefix: production
insecureSkipTLSVerify: false
pitr:
enabled: true
oplogOnly: false
compressionType: gzip
tasks:
- name: daily-full
enabled: true
schedule: "0 3 * * *"
keep: 7
storageName: s3-backup
compressionType: gzip
secrets:
users: mongodb-users-secret
pmm:
enabled: true
image: percona/pmm-client:2
serverHost: pmm-server.monitoringPercona Operator 的主要優勢是其與 Percona Backup for MongoDB (PBM) 的整合備份管理。 PBM 支援邏輯和物理備份、增量備份以及操作日誌的時間點恢復 — 所有這些都透過 CRD 以宣告方式配置。
AWS 部署:DocumentDB 與 Atlas 與 EKS
上的自我管理Amazon DocumentDB是與 MongoDB 相容的文件資料庫服務。它不是 MongoDB — 它是實現 MongoDB 有線協議(最高相容 MongoDB 4.0 API)的專有引擎。 DocumentDB 使用類似於 Aurora 的分散式儲存層將計算與儲存分開。它提供區域內的自動故障轉移、最多 15 個只讀副本和時間點恢復。然而,它缺乏許多 MongoDB 功能:更改流有限制、事務工作方式不同以及許多聚合管道階段不受支援。僅當您的應用程式使用 MongoDB 的 API 的子集並且您重視完全託管服務的操作簡單性時,才使用 DocumentDB。
AWS 上的 MongoDB Atlas是在 AWS 基礎設施上執行的 MongoDB 自己的託管服務。它提供真正的 MongoDB 的所有功能、自動化 HA、連續備份、時間點恢復、自動擴充套件和多區域叢集。 Atlas 是生產 MongoDB 的最簡單途徑,但規模化時也是最昂貴的選擇。
在 EKS上進行自我管理,讓您可以完全控制 MongoDB 版本、配置和成本。將 MongoDB Community Operator 或 Percona Operator 與 EBS gp3 儲存和服務帳戶的 IAM 角色 (IRSA) 結合使用,以實現安全的 S3 備份訪問。
# EBS StorageClass optimised for MongoDB
apiVersion: storage.k8s.io/v1
kind: StorageClass
metadata:
  name: gp3-csi
provisioner: ebs.csi.aws.com
parameters:
  type: gp3
  iops: "6000"
  throughput: "250"
  encrypted: "true"
volumeBindingMode: WaitForFirstConsumer
allowVolumeExpansion: true
reclaimPolicy: Retain
# IRSA for backup S3 access
eksctl create iamserviceaccount \
--name mongodb-backup-sa \
--namespace databases \
--cluster my-eks-cluster \
--attach-policy-arn arn:aws:iam::111122223333:policy/MongoDBBackupS3Policy \
--approveAzure 部署:Cosmos DB、Atlas 與 AKS
上的自我管理Azure Cosmos DB for MongoDB (vCore)是最接近真實 MongoDB 的 Azure 本機產品。 與適用於 MongoDB 的舊版基於 RU 的 Cosmos DB API 不同,vCore 模型在專用計算上執行實際的 MongoDB 引擎例項,提供與 MongoDB 6.0+ 功能的高度相容性,包括完整的聚合管道、更改流和事務。它提供區域冗餘 HA、時間點恢復和自動備份。
Azure上的 MongoDB Atlas 提供與 AWS 相同的完全託管的 MongoDB 體驗,在具有 VNET 對等互連、Azure 專用鏈路和 Azure AD 整合的 Azure 基礎設施上執行。
在 AKS 上進行自我管理將 Azure 託管磁碟(推薦使用 Premium SSD v2)與 MongoDB 或 Percona Operator 結合使用。
# Azure Premium SSD StorageClass
apiVersion: storage.k8s.io/v1
kind: StorageClass
metadata:
  name: azure-premium-mongodb
provisioner: disk.csi.azure.com
parameters:
  skuName: Premium_LRS
  cachingMode: None
volumeBindingMode: WaitForFirstConsumer
allowVolumeExpansion: true
reclaimPolicy: Retain
GCP 部署:GCP 上的 Atlas 與 GKE
上的自我管理 GCP 上的MongoDB Atlas在 Google Cloud 基礎架構上執行,具有 GCP 原生整合:VPC 對等互連、Private Service Connect 和 GKE 叢集整合。 Atlas on GCP 支援跨 GCP 區域的多區域叢集,並具有自動故障轉移功能。
在 GKE 上進行自我管理將持久磁碟 SSD 與 MongoDB 或 Percona 運算子結合使用。 GKE Workload Identity 為 GCS 備份提供安全、無金鑰的身份驗證。
# GKE SSD StorageClass
apiVersion: storage.k8s.io/v1
kind: StorageClass
metadata:
  name: pd-ssd-mongodb
provisioner: pd.csi.storage.gke.io
parameters:
  type: pd-ssd
volumeBindingMode: WaitForFirstConsumer
allowVolumeExpansion: true
reclaimPolicy: Retain
裸機 k3s/帶 Longhorn
的 Rancher為了資料主權、合規性或成本最佳化,MongoDB 使用具有 Rancher 管理和 Longhorn 分散式儲存的 k3s 在裸機 Kubernetes 上有效執行。該架構消除了對雲提供商的依賴,同時保持相同的基於運營商的管理模型。
適用於 MongoDB 的 Longhorn 儲存
# Install Longhorn
helm repo add longhorn https://charts.longhorn.io
helm repo update

helm install longhorn longhorn/longhorn \
  --namespace longhorn-system \
  --create-namespace \
  --set defaultSettings.defaultReplicaCount=3 \
  --set defaultSettings.storageMinimalAvailablePercentage=15

# StorageClass for MongoDB on Longhorn
apiVersion: storage.k8s.io/v1
kind: StorageClass
metadata:
  name: longhorn-mongo
provisioner: driver.longhorn.io
parameters:
  numberOfReplicas: "3"
  staleReplicaTimeout: "2880"
  dataLocality: best-effort
  fsType: xfs
volumeBindingMode: WaitForFirstConsumer
allowVolumeExpansion: true
reclaimPolicy: RetainXFS,而不是 ext4。 MongoDB 的 WiredTiger 儲存引擎受益於 XFS 的分配模式,特別是對於日誌和資料檔案。 Longhorn 的三向複製在 MongoDB 的副本集級冗餘之上提供卷級冗餘,為您提供針對儲存故障的深度防禦。
MetalLB 和無頭服務
# MetalLB IP Pool for MongoDB
apiVersion: metallb.io/v1beta1
kind: IPAddressPool
metadata:
  name: mongo-pool
  namespace: metallb-system
spec:
  addresses:
    - 192.168.1.220-192.168.1.225
---
apiVersion: metallb.io/v1beta1
kind: L2Advertisement
metadata:
  name: mongo-l2
  namespace: metallb-system
spec:
  ipAddressPools:
    - mongo-pool
MongoDB 操作員建立一個無頭服務,為每個 Pod 提供穩定的 DNS 名稱 (mongo-0.mongo-svc.databases.svc.cluster.local)。這對於副本整合員發現至關重要。如果您需要外部訪問,MetalLB 會為 mongos 路由器(對於分片叢集)或主路由器(對於副本集)前面的 LoadBalancer 服務分配可路由的 IP。
備份策略
MongoDB提供多種備份方法,每種方法適合不同的場景。
mongodump / mongorestore
匯出 BSON 文件的邏輯備份。行動式且可供人工檢查,但對於大型資料集來說速度較慢,並且本身不支援時間點恢復。
# Full logical backup with oplog for consistency
mongodump --uri="mongodb://backup-user:password@mongo-0:27017,mongo-1:27017,mongo-2:27017/appdb?replicaSet=rs-production&authSource=admin" \
  --oplog \
  --gzip \
  --out=/backups/$(date +%Y%m%d-%H%M%S)

# Restore
mongorestore --uri="mongodb://admin:password@mongo-0:27017/?replicaSet=rs-production&authSource=admin" \
  --oplogReplay \
  --gzip \
  /backups/20260412-030000/
適用於 MongoDB 的 Percona 備份 (PBM)
PBM 提供物理備份、增量備份和時間點恢復。它是生產中自我管理的 MongoDB 的推薦備份工具。
# Configure PBM storage
pbm config --set storage.type=s3 \
  --set storage.s3.bucket=company-mongodb-backups \
  --set storage.s3.region=us-east-1 \
  --set storage.s3.credentials.access-key-id=$AWS_ACCESS_KEY \
  --set storage.s3.credentials.secret-access-key=$AWS_SECRET_KEY

# Full backup
pbm backup --type=logical --compression=gzip

# Physical backup (faster, requires WiredTiger)
pbm backup --type=physical --compression=gzip

# Incremental backup
pbm backup --type=incremental --base-snapshot=2026-04-12T03:00:00Z

# Point-in-time recovery
pbm restore --time="2026-04-12T09:30:00Z"

# List backups
pbm list

# Check backup status
pbm status
雲快照
在雲提供商上,EBS 快照 (AWS)、託管磁碟快照 (Azure) 和持久磁碟快照 (GCP) 提供快速的儲存級備份。與db.fsyncLock()結合以實現時間點一致性,它們可為大型資料集提供最快的備份和恢復時間。
# Kubernetes VolumeSnapshot for MongoDB
apiVersion: snapshot.storage.k8s.io/v1
kind: VolumeSnapshot
metadata:
  name: mongodb-snapshot-$(date +%Y%m%d)
  namespace: databases
spec:
  volumeSnapshotClassName: csi-snapclass
  source:
    persistentVolumeClaimName: data-volume-production-mongodb-0
基於 Oplog 的時間點恢復
oplog 與基礎備份結合使用時可實現時間點恢復 (PITR)。 PBM 持續將 oplog 條目存檔到備份儲存。為了恢復到特定時間點,PBM 恢復最新的基礎備份,然後重播 oplog 條目直至目標時間戳。這是透過pitr部分在 Percona Operator CRD 中配置的。
連線字串配置
正確的連線字串配置對於故障轉移事件期間的應用程式恢復能力至關重要。
# Standard connection string with all replica set members
mongodb://appuser:password@mongo-0.mongo-svc:27017,mongo-1.mongo-svc:27017,mongo-2.mongo-svc:27017/appdb?replicaSet=rs-production&w=majority&j=true&readPreference=secondaryPreferred&retryWrites=true&retryReads=true&connectTimeoutMS=10000&socketTimeoutMS=30000&serverSelectionTimeoutMS=15000&maxPoolSize=100&minPoolSize=10

# SRV-based connection string (DNS discovery)
mongodb+srv://appuser:password@mongo-cluster.databases.svc.cluster.local/appdb?w=majority&retryWrites=true&readPreference=nearest

# For sharded clusters (connect through mongos)
mongodb://appuser:password@mongos-0:27017,mongos-1:27017/appdb?w=majority&retryWrites=true&readPreference=nearest
HA 的關鍵連線字串引數:retryWrites=true和retryReads=true可自動重試在故障轉移期間失敗的操作。w=majority確保寫入在初選中倖存下來。serverSelectionTimeoutMS控制驅動程式等待找到合適伺服器的時間 - 將其設定為高於預期的選舉時間(至少 15 秒)。maxPoolSize限制每個 mongos/副本整合員的連線池,以防止連線耗盡。
索引最佳化和查詢效能
索引是 MongoDB 查詢效能的主要槓桿。頻繁查詢的欄位上缺少索引會強制進行集合掃描,該掃描會隨著資料大小線性降低。
# Create compound index for common query pattern
db.orders.createIndex(
  { customer_id: 1, order_date: -1, status: 1 },
  { name: "idx_customer_orders", background: true }
)

# Partial index (only index documents matching a filter)
db.events.createIndex(
  { timestamp: 1 },
  { name: "idx_active_events", partialFilterExpression: { status: "active" } }
)

# TTL index for automatic document expiration
db.sessions.createIndex(
  { createdAt: 1 },
  { expireAfterSeconds: 86400, name: "idx_session_ttl" }
)

# Text index for search
db.products.createIndex(
  { name: "text", description: "text" },
  { weights: { name: 10, description: 5 }, name: "idx_product_search" }
)

# Analyze query performance
db.orders.find({ customer_id: "c123" }).sort({ order_date: -1 }).explain("executionStats")

# Find unused indexes
db.orders.aggregate([ { $indexStats: {} } ])定期檢查$indexStats,以識別浪費儲存空間和降低寫入速度的未使用索引。使用explain()方法驗證查詢是否使用預期索引,並檢查totalDocsExamined相對於nReturned是否較高,這表明查詢計劃效率低下。
WiredTiger 儲存引擎調整
WiredTiger 是 MongoDB 自 MongoDB 4.2 以來的預設且唯一的生產儲存引擎。其效能特徵很大程度上受到快取大小、壓縮和日誌配置的影響。
# WiredTiger configuration in mongod.conf
storage:
  dbPath: /data/db
  journal:
    enabled: true
    commitIntervalMs: 100
  wiredTiger:
    engineConfig:
      cacheSizeGB: 4            # ~50% of (RAM - 1GB), max 80%
      journalCompressor: snappy
      directoryForIndexes: true  # separate dir for index files
    collectionConfig:
      blockCompressor: snappy   # or zstd for better ratio
    indexConfig:
      prefixCompression: true

operationProfiling:
  mode: slowOp
  slowOpThresholdMs: 100

replication:
  oplogSizeMB: 51200            # 50 GB oplog
  replSetName: rs-production

net:
  maxIncomingConnections: 10000
  compression:
    compressors: snappy,zstd,zlib

setParameter:
  wiredTigerConcurrentReadTransactions: 128
  wiredTigerConcurrentWriteTransactions: 128
WiredTiger 快取的大小應足以容納您的工作集 — 由查詢主動訪問的資料和索引。如果快取太小,WiredTiger 會頻繁驅逐頁面,導致 I/O 高。如果太大,則會為作業系統檔案系統快取和其他程序留下足夠的記憶體。起點是可用 RAM 的 50% 減去 1 GB(用於作業系統和其他程序),上限為工作集大小。
身份驗證和 TLS 加密
# Generate TLS certificates for MongoDB
# CA certificate
openssl req -x509 -newkey rsa:4096 -days 3650 -nodes \
  -keyout ca.key -out ca.crt \
  -subj "/CN=MongoDB-CA"

# Server certificate (include all member hostnames in SAN)
openssl req -newkey rsa:4096 -nodes \
  -keyout server.key -out server.csr \
  -subj "/CN=mongo-0.mongo-svc.databases.svc.cluster.local" \
  -addext "subjectAltName=DNS:mongo-0.mongo-svc.databases.svc.cluster.local,DNS:mongo-1.mongo-svc.databases.svc.cluster.local,DNS:mongo-2.mongo-svc.databases.svc.cluster.local,DNS:localhost,IP:127.0.0.1"

openssl x509 -req -in server.csr -CA ca.crt -CAkey ca.key \
  -CAcreateserial -out server.crt -days 365

# Combine cert and key into PEM
cat server.crt server.key > server.pem

# Create Kubernetes secrets
kubectl create secret tls mongodb-tls-cert \
  --cert=server.crt --key=server.key -n databases

kubectl create secret generic mongodb-ca-cert \
  --from-file=ca.crt=ca.crt -n databases
# MongoDB TLS configuration (mongod.conf)
net:
tls:
mode: requireTLS
certificateKeyFile: /etc/mongodb/tls/server.pem
CAFile: /etc/mongodb/tls/ca.crt
allowConnectionsWithoutCertificates: false
security:
authorization: enabled
clusterAuthMode: x509使用 Prometheus 和 Grafana 進行監控
MongoDB 透過與 Prometheus 整合的mongodb_exporter(來自 Percona)公開指標。要監控的關鍵指標包括連線計數、操作率、複製延遲、WiredTiger 快取使用情況和查詢目標效率。
# Deploy mongodb_exporter as a sidecar or standalone
apiVersion: apps/v1
kind: Deployment
metadata:
  name: mongodb-exporter
  namespace: databases
spec:
  replicas: 1
  selector:
    matchLabels:
      app: mongodb-exporter
  template:
    metadata:
      labels:
        app: mongodb-exporter
      annotations:
        prometheus.io/scrape: "true"
        prometheus.io/port: "9216"
    spec:
      containers:
        - name: exporter
          image: percona/mongodb_exporter:0.40.0
          args:
            - --mongodb.uri=mongodb://monitoring:password@production-mongodb-0.production-mongodb-svc:27017,production-mongodb-1.production-mongodb-svc:27017,production-mongodb-2.production-mongodb-svc:27017/?replicaSet=rs-production&authSource=admin
            - --collect-all
            - --compatible-mode
          ports:
            - containerPort: 9216
          resources:
            requests:
              cpu: 100m
              memory: 128Mi
# ServiceMonitor for Prometheus Operator
apiVersion: monitoring.coreos.com/v1
kind: ServiceMonitor
metadata:
name: mongodb-metrics
namespace: databases
labels:
release: kube-prometheus-stack
spec:
selector:
matchLabels:
app: mongodb-exporter
endpoints:
- port: metrics
interval: 15s
scrapeTimeout: 10s# Critical Prometheus alert rules for MongoDB
apiVersion: monitoring.coreos.com/v1
kind: PrometheusRule
metadata:
name: mongodb-alerts
namespace: databases
labels:
release: kube-prometheus-stack
spec:
groups:
- name: mongodb-health
rules:
- alert: MongoDBReplicationLagHigh
expr: mongodb_mongod_replset_member_replication_lag > 30
for: 5m
labels:
severity: warning
annotations:
summary: "MongoDB replica {{ $labels.name }} lag exceeds 30s"
- alert: MongoDBConnectionsHigh
expr: mongodb_connections{state="current"} / mongodb_connections{state="available"} > 0.8
for: 2m
labels:
severity: critical
annotations:
summary: "MongoDB connections above 80% capacity"
- alert: MongoDBWiredTigerCacheEvictions
expr: rate(mongodb_wiredtiger_cache_evicted_pages_total[5m]) > 100
for: 10m
labels:
severity: warning
annotations:
summary: "High WiredTiger cache eviction rate"
- alert: MongoDBReplicaSetNoPrimary
expr: mongodb_mongod_replset_number_of_members{state="PRIMARY"} == 0
for: 1m
labels:
severity: critical
annotations:
summary: "MongoDB replica set has no primary"
- alert: MongoDBQueryTargetingInefficient
expr: rate(mongodb_mongod_metrics_query_executor_total{state="scanned_objects"}[5m]) / rate(mongodb_mongod_metrics_query_executor_total{state="returned"}[5m]) > 100
for: 15m
labels:
severity: warning
annotations:
summary: "MongoDB scanning 100x more documents than returned"更改實時應用程式的流
更改流為 MongoDB 中的資料更改提供實時通知機制。他們利用 oplog 將更改事件推送到應用程式,從而實現事件驅動的架構、實時儀表板和無需輪詢的資料同步管道。
// Watch changes on a collection
const pipeline = [
  { $match: { operationType: { $in: ["insert", "update", "replace"] } } },
  { $match: { "fullDocument.status": "active" } }
];

const changeStream = db.collection("orders").watch(pipeline, {
  fullDocument: "updateLookup",  // include full document on updates
  resumeAfter: resumeToken       // resume from last processed event
});

changeStream.on("change", (change) => {
  console.log("Change detected:", change.operationType);
  console.log("Document:", change.fullDocument);
  // Store resume token for crash recovery
  saveResumeToken(change._id);
});

changeStream.on("error", (error) => {
  console.error("Change stream error:", error);
  // Reconnect using saved resume token
});
更改流需要副本集或分片叢集(它們不適用於獨立的 mongod 例項)。它們在初選中倖存下來 - 驅動程式自動重新連線並從上次收到的恢復令牌恢復。對於生產使用,請始終保留恢復令牌,以便您的應用程式可以從重新啟動中恢復而不會丟失事件。
滾動維護和版本升級
MongoDB 支援滾動升級,一次升級一個副本整合員,從輔助副本開始,到主副本結束(這會觸發降級和選舉)。這允許對次要和主要版本更改進行零停機升級。
# Rolling upgrade procedure for self-managed replica set
# 1. Upgrade each secondary one at a time
# On secondary (mongo-2):
sudo systemctl stop mongod
sudo yum install -y mongodb-org-7.0.14  # or apt-get
sudo systemctl start mongod
# Wait for the member to reach SECONDARY state
rs.status()

# 2. Step down the primary
rs.stepDown()

# 3. Upgrade the old primary (now a secondary)
sudo systemctl stop mongod
sudo yum install -y mongodb-org-7.0.14
sudo systemctl start mongod

# 4. Verify cluster health
rs.status()
db.adminCommand({ getParameter: 1, featureCompatibilityVersion: 1 })

# 5. Set feature compatibility version (irreversible)
db.adminCommand({ setFeatureCompatibilityVersion: "7.0" })
透過 MongoDB Community Operator 或 Kubernetes 上的 Percona Operator,滾動升級是自動化的 — 您只需更新 CRD 中的version欄位,操作員就會處理每個 Pod 的滾動更新,等待每個成員變得健康後再繼續。
災難恢復和故障轉移測試
從未在故障下進行過測試的高可用性部署未經測試。定期故障轉移測試可驗證您的架構、監控警報以及團隊的事件響應程式。
受控故障轉移測試
# Test 1: Step down the primary
rs.stepDown(120)  // 120-second election hold
// Monitor: election should complete in ~10-12s
// Verify: application reconnects and resumes operations

# Test 2: Kill a secondary pod in Kubernetes
kubectl delete pod production-mongodb-1 -n databases --grace-period=0 --force
// The StatefulSet recreates the pod
// The operator rejoins it to the replica set

# Test 3: Simulate network partition
kubectl exec production-mongodb-0 -n databases -- \
  iptables -A INPUT -p tcp --dport 27017 -j DROP
// The isolated primary should step down (cannot reach majority)
// Remaining members elect a new primary
// Cleanup: remove iptables rule and let member rejoin

# Test 4: Simulate storage failure
kubectl exec production-mongodb-2 -n databases -- \
  chmod 000 /data/db
// mongod should crash; Kubernetes restarts the pod
// The member resyncs from the primary's oplog
故障轉移期間測量什麼
- RTO(恢復時間目標)— 從主要故障到新主要接受寫入的時間。目標:副本集不到 30 秒。
- RPO(恢復點目標)— 故障轉移期間資料丟失。對於
w: majority,確認寫入的 RPO 為零。對於w: 1,RPO 等於發生故障時的複製滯後。 - 應用程式錯誤率— 故障轉移視窗期間失敗的請求的百分比。使用
retryWrites=true時,大多數寫入失敗都會由驅動程式自動重試。 - 更改流連續性— 驗證更改流使用者是否從其儲存的令牌恢復而不會丟失事件。
災難恢復執行手冊
- 單成員故障— 透過 Kubernetes Pod 重啟和 oplog 追趕自動恢復。除非成員需要完全重新同步,否則不需要手動操作。
- 主節點故障— 自動選舉會在 10-12 秒內升級輔助節點。 驗證剩餘輔助節點上的應用程式連線和複製延遲。
- 多數失敗— 如果大多數成員出現故障,副本集將變為只讀(無法進行選舉)。恢復成員或使用
rs.reconfig({ force: true })作為最後的手段(這可能會導致資料丟失)。 - 叢集完全丟失— 部署新叢集,從最新的 PBM 備份恢復,並將 oplog 重播到目標時間點。更新連線字串和 DNS 記錄。
- 區域故障轉移— 如果主要區域丟失,則另一個區域中的輔助區域會自動選舉為主要區域(如果它具有足夠的優先順序並且其餘成員佔多數)。更新 DNS 以將流量路由到新的主要區域。
生產調整建議
作業系統級調整
# Disable Transparent Huge Pages (critical for MongoDB)
echo never > /sys/kernel/mm/transparent_hugepage/enabled
echo never > /sys/kernel/mm/transparent_hugepage/defrag

# Set readahead to 8-32 sectors for SSD
blockdev --setra 32 /dev/sda

# Increase file descriptor limits
ulimit -n 64000
ulimit -u 64000

# Swappiness
vm.swappiness = 1

# Dirty page ratio
vm.dirty_ratio = 15
vm.dirty_background_ratio = 5

# Network tuning
net.core.somaxconn = 4096
net.ipv4.tcp_max_syn_backlog = 4096
net.ipv4.tcp_keepalive_time = 120
資源大小指南
- WiredTiger 快取:可用 RAM 的 50% 減去 1 GB,或工作集的大小,以較小者為準。
- Oplog 大小:足以容納 24-72 小時的寫入操作。從 50 GB 開始並使用
rs.printReplicationInfo()進行監控。 - 儲存 IOPS:MongoDB 是 I/O 密集型,尤其是在壓縮和檢查點期間。使用具有預配置 IOPS 的 NVMe SSD 或雲端儲存(AWS 上具有 6000+ IOPS 的 gp3、Azure 上的 Premium SSD v2、GCP 上的 pd-ssd)。
- CPU:MongoDB 受益於併發讀/寫操作、WiredTiger 的併發事務和後臺任務(檢查點、壓縮、複製)的多個核心。
- 網路:複製流量對於寫入密集型工作負載可能非常重要。確保副本整合員之間的低延遲、高頻寬網路。
連線管理
# Application-side connection pool configuration
const client = new MongoClient(uri, {
  maxPoolSize: 100,
  minPoolSize: 10,
  maxIdleTimeMS: 60000,
  waitQueueTimeoutMS: 5000,
  connectTimeoutMS: 10000,
  socketTimeoutMS: 30000,
  serverSelectionTimeoutMS: 15000,
  retryWrites: true,
  retryReads: true,
  w: "majority",
  readPreference: "secondaryPreferred",
  compressors: ["snappy", "zstd"]
});
監控清單
- 複製延遲— 當任何輔助節點延遲超過 30 秒時發出警報。
- 連線飽和— 當前連線超過
maxIncomingConnections的 80% 時發出警報。 - WiredTiger 快取— 當快取髒填充率超過 20% 時發出警報(表示寫入壓力超過檢查點吞吐量)。
- Oplog 視窗— 當 oplog 視窗低於 12 小時時發出警報(維護後輔助節點需要完全重新同步的風險)。
- 查詢目標— 當掃描文件與返回文件的比率超過 100(缺少索引)時發出警報。
- 磁碟使用情況— 在 70% 和 85% 閾值時發出警報。 MongoDB 在壓縮期間可以使用大量臨時磁碟空間。
- 備份新鮮度— 當上次成功備份早於 RPO 視窗時發出警報。
- 票證可用性— 監控 WiredTiger 讀寫票證。耗盡會導致操作排隊和延遲峰值。
操作命令快速參考
# Replica set status
rs.status()
rs.conf()
rs.printReplicationInfo()
rs.printSecondaryReplicationInfo()

# Cluster health (sharded)
sh.status()
db.adminCommand({ balancerStatus: 1 })
db.adminCommand({ listShards: 1 })

# Server diagnostics
db.serverStatus()
db.currentOp({ "$all": true })
db.adminCommand({ hostInfo: 1 })

# Kill long-running operations
db.killOp(opId)

# Compaction (reclaim disk space)
db.runCommand({ compact: "orders" })

# Profiler (identify slow queries)
db.setProfilingLevel(1, { slowms: 100 })
db.system.profile.find().sort({ ts: -1 }).limit(10)

# Index management
db.orders.getIndexes()
db.orders.createIndex({ field: 1 }, { background: true })
db.orders.dropIndex("index_name")

# Kubernetes-specific
kubectl get mongodbcommunity -n databases
kubectl describe mongodbcommunity production-mongodb -n databases
kubectl logs production-mongodb-0 -n databases -c mongod
kubectl exec -it production-mongodb-0 -n databases -c mongod -- mongosh
決策矩陣:選擇 MongoDB HA 架構
- 單雲、託管首選項— 使用 MongoDB Atlas。它以最小的運營開銷處理高可用性、備份、監控和擴充套件。
- 與 MongoDB 相容的 AWS 僅需要— 如果您的應用程式使用 MongoDB API 的基本子集並且您想要完全託管的體驗,請考慮 Amazon DocumentDB。 否則,Atlas 或在 EKS 上進行自我管理。
- 具有完整 MongoDB 功能的 Azure— 使用適用於 MongoDB vCore 的 Cosmos DB 來獲得託管體驗,或使用 Azure 上的 Atlas 來獲得真正的 MongoDB 託管服務。
- 多雲或混合— 透過 MongoDB Community Operator 或 Percona Operator 進行自我管理。 Kubernetes 抽象支援跨提供商的一致部署。
- 裸機或邊緣— k3s + Rancher + Longhorn + MongoDB 社群運營商或 Percona 運營商。無需雲依賴。
- 大規模水平擴充套件— 具有資料區域性性區域分片的分片叢集。使用原生支援分片部署的 Percona Operator。
- 實時事件驅動應用— MongoDB 更改流提供內建 CDC。確保您使用副本集或分片叢集(不是獨立的)。
結論
MongoDB 的內建複製和分片原語賦予其高可用性的架構優勢 - 具有自動故障轉移功能的副本集和具有水平擴充套件功能的分片叢集是本機功能,而不是事後附加的功能。但這些原語必須正確配置並嚴格操作,才能提供生產系統所需的可用性保證。
生產 MongoDB 部署需要跨故障域的三個資料承載副本整合員、w: majority寫入永續性、適當的操作日誌大小以實現複製彈性、針對工作集的 WiredTiger 快取調整以及具有時間點恢復功能的經過測試的備份策略。 Kubernetes Operator(無論是用於副本集的 MongoDB Community Operator,還是用於包括分片和整合備份在內的全功能部署的 Percona Operator)可實現生命週期管理的自動化,否則需要大量的運營投資。
AWS、Azure、GCP 和裸機的部署模式共享相同的核心 MongoDB 配置。改變的是儲存類別、備份目標和網路層。這種一致性是基於操作員的方法的價值:您的團隊學習一種工具、一種操作模型和一套適用於任何地方的操作手冊。
從三成員副本集開始,w: majority寫入、具有連續 oplog 歸檔的每日 PBM 備份,以及針對複製滯後、連線飽和和快取壓力的核心 Prometheus 警報。在第一天測試您的故障轉移——而不是在第一次事件期間。隨著資料量和可用性要求的增長,擴充套件到分片、基於區域的資料區域性性和多區域部署。基礎設施處理機械;您的責任是足夠深入地瞭解架構,以便針對您的工作負載做出正確的權衡,並不斷地測試這些假設。