The Workstation Blog
AI
Posts tagged AI.
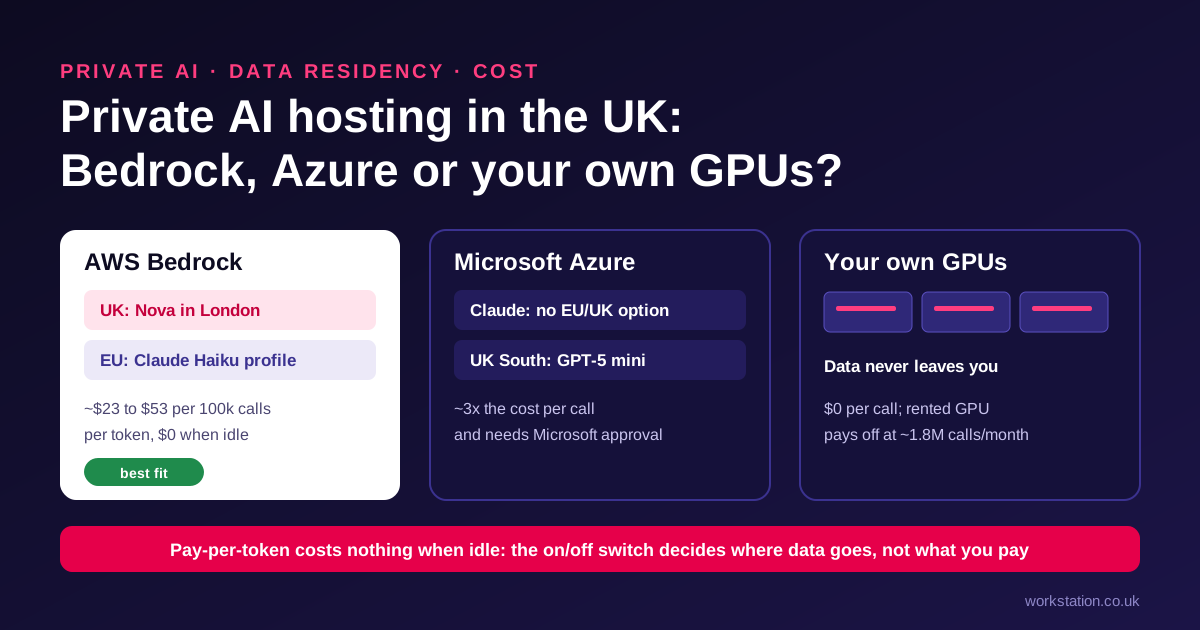
Private AI Hosting in the UK: AWS Bedrock vs Microsoft Azure vs Your Own GPUs
Where is customer financial data processed, and what does each AI call cost? A comparison of AWS Bedrock, Microsoft Azure, UK and EU AI providers and your own GPUs for a typical UK finance workload, with costs at three volumes, a data-residency workflow and the break-even point for a dedicated GPU.
 WorkstationRead
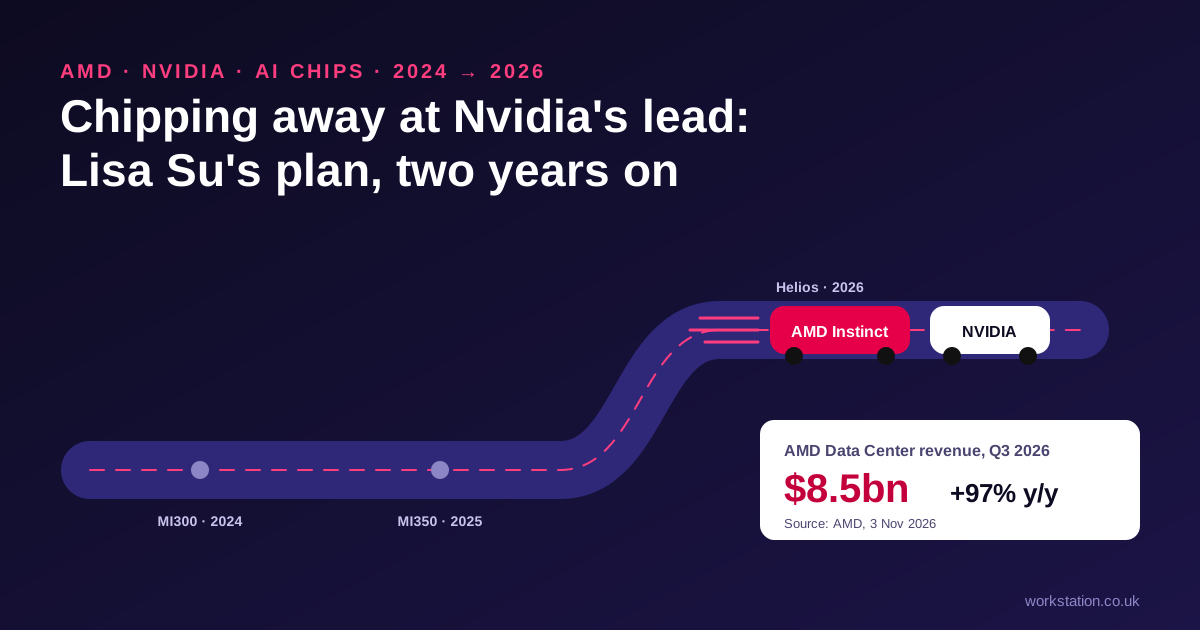
Chipping Away at Nvidia's Lead: Lisa Su's AMD Plan, Two Years On
In December 2024 Bloomberg's The Circuit asked AMD CEO Lisa Su how she would chip away at Nvidia's lead in AI. We check the plan against AMD's 2026 results and Helios launch, and explain what a credible second AI platform means for UK buyers. Includes a link to the interview.
WorkstationRead 
Build AI Agents with NebulaDB: Semantic Search, RAG and a Visa AI Agent
How we built semantic search, RAG and a Thai Visa AI Agent on NebulaDB, with real queries, query plans and retrieval scores measured on our 8.3M-document production server, and the guards that keep private data and invented numbers out of the answers.
Balinder WaliaRead 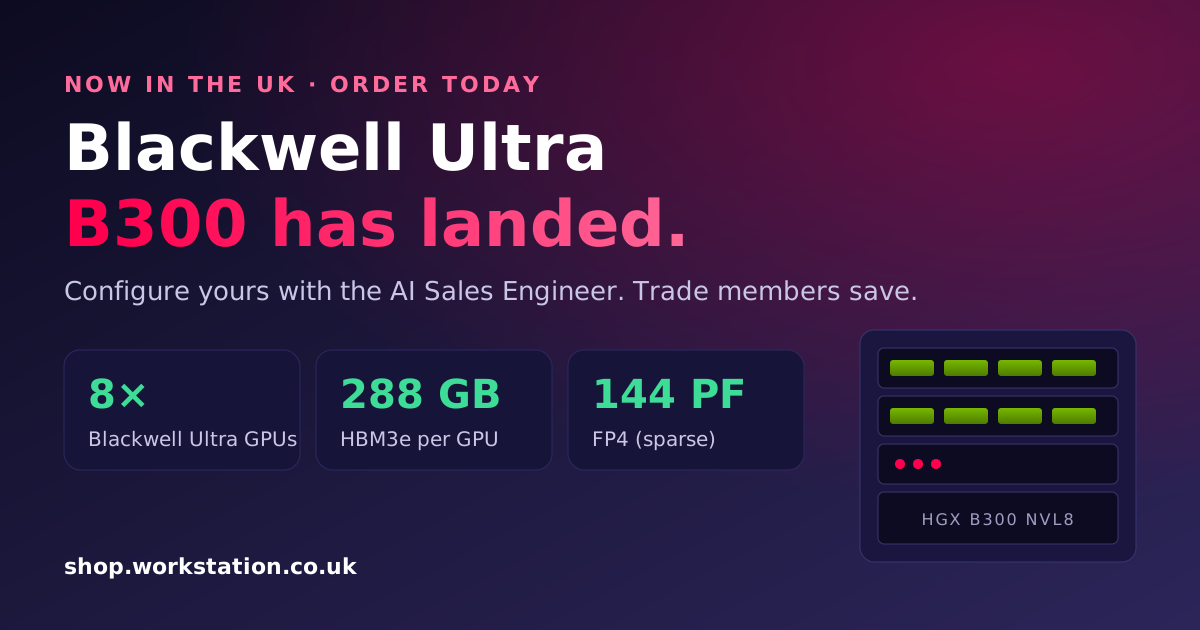
NVIDIA Blackwell Ultra B300 Has Landed in the UK: Configure Yours Today
NVIDIA Blackwell Ultra B300 systems have arrived with our UK distribution partners. Configure and price your eight-GPU B300 build in minutes with our AI Sales Engineer, save with Workstation Trade, and order today to be first in line as UK supply arrives.
Balinder WaliaRead 
Private AI for Law Firms: Choosing an Offline-First Workstation Your Clients Can Trust
How a law firm chooses a private-AI workstation that runs with no internet connection: who uses it, which model, how much GPU memory, how isolated it must be and who sets it up. With real prices from a real quote, where it was over-specified, and the Starter, Workforce and Enterprise builds we would actually ship.
Balinder WaliaRead 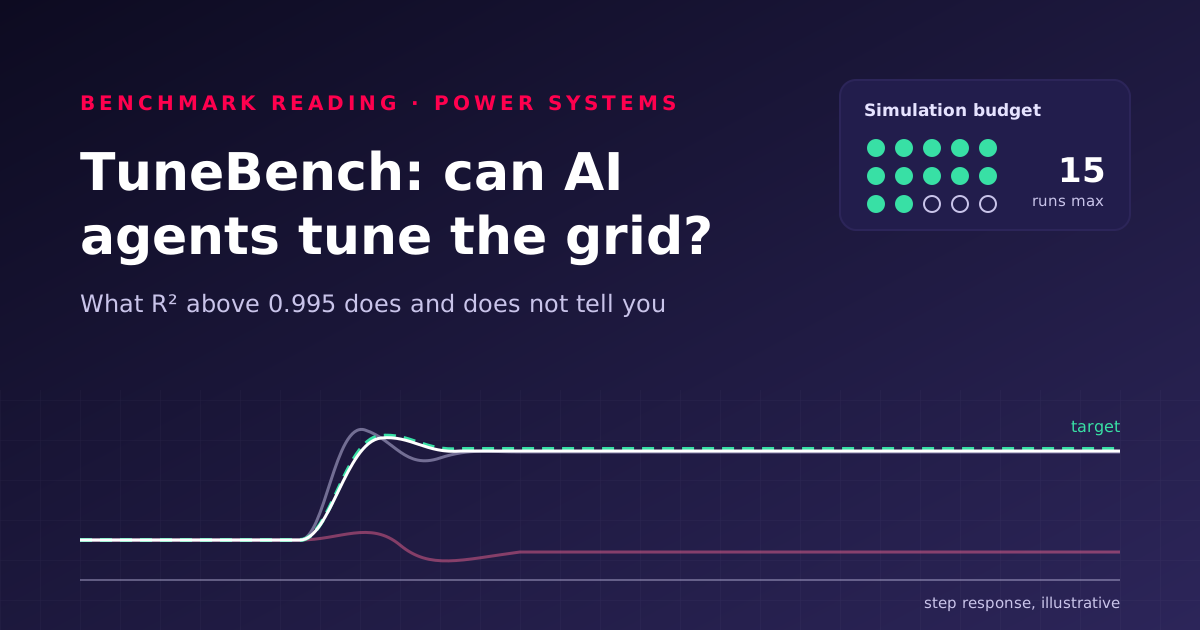
TuneBench: How Well Can AI Agents Calibrate Power System Models?
TuneBench tests LLM agents on calibrating generator and battery models within 15 simulations. Only Opus 5.5 and GPT-6 hit median R² above 0.995 in every test. What that figure means, its limits, and how to build the same kind of benchmark.
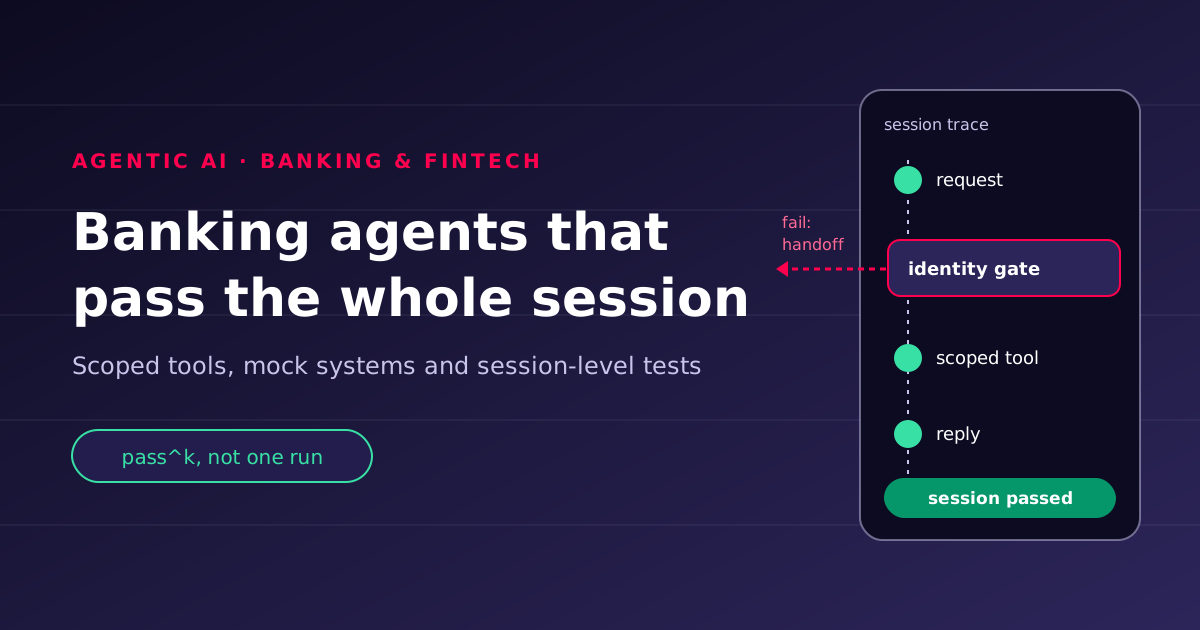
Agentic AI in banking: efficiency you can defend to a risk committee
Banking AI agents rarely fail on one bad reply; they fail across a session. How to scope tools, test whole conversations against mock systems and measure reliability with pass^k, so the time saved survives audit and production.
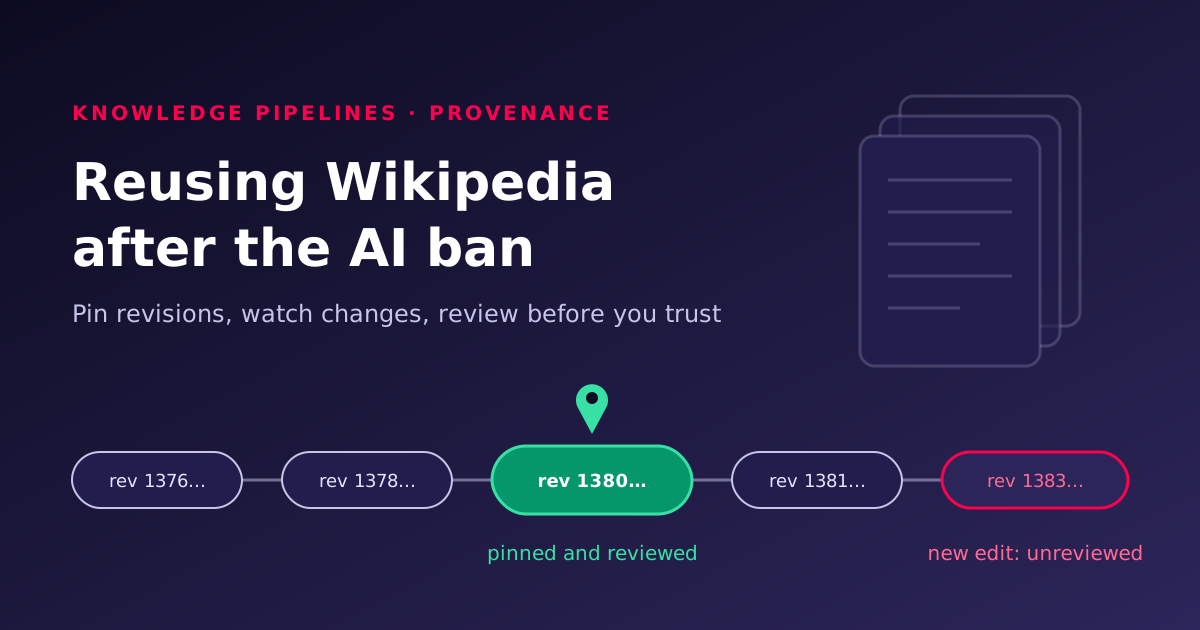
Wikipedia banned AI-written articles: what teams that reuse it should change
English Wikipedia now prohibits LLM-written article text, yet volunteers still flag a steady share of new drafts as AI-generated. If your search, chatbot or knowledge base reuses Wikipedia, here is how to pin revisions, watch edits, review changes and attribute correctly.
Trading costs with agents: what an AI agent really costs to run
AI agents move cost rather than remove it. Learn why the token bill grows with the square of loop steps, how caching and compaction bend the curve, and a playbook for pricing, budgeting and capping an agent before it reaches production.
The energy cost of LLM code optimisation, and when it pays back
A 2026 study found LLM-optimised code used more energy per run than the human reference in 42 of 44 configurations. Learn the break-even rule, how to measure joules per run on Linux, and a workflow for keeping only the rewrites that pay back.